
方法与流程
一个像素,两个表面点
沿相机射线,最近和最远的表面交点分别对应前、后表面。HccePose(BF) 预测两个表面的层次化连续坐标编码,并将解码后的三维点与图像像素配对。
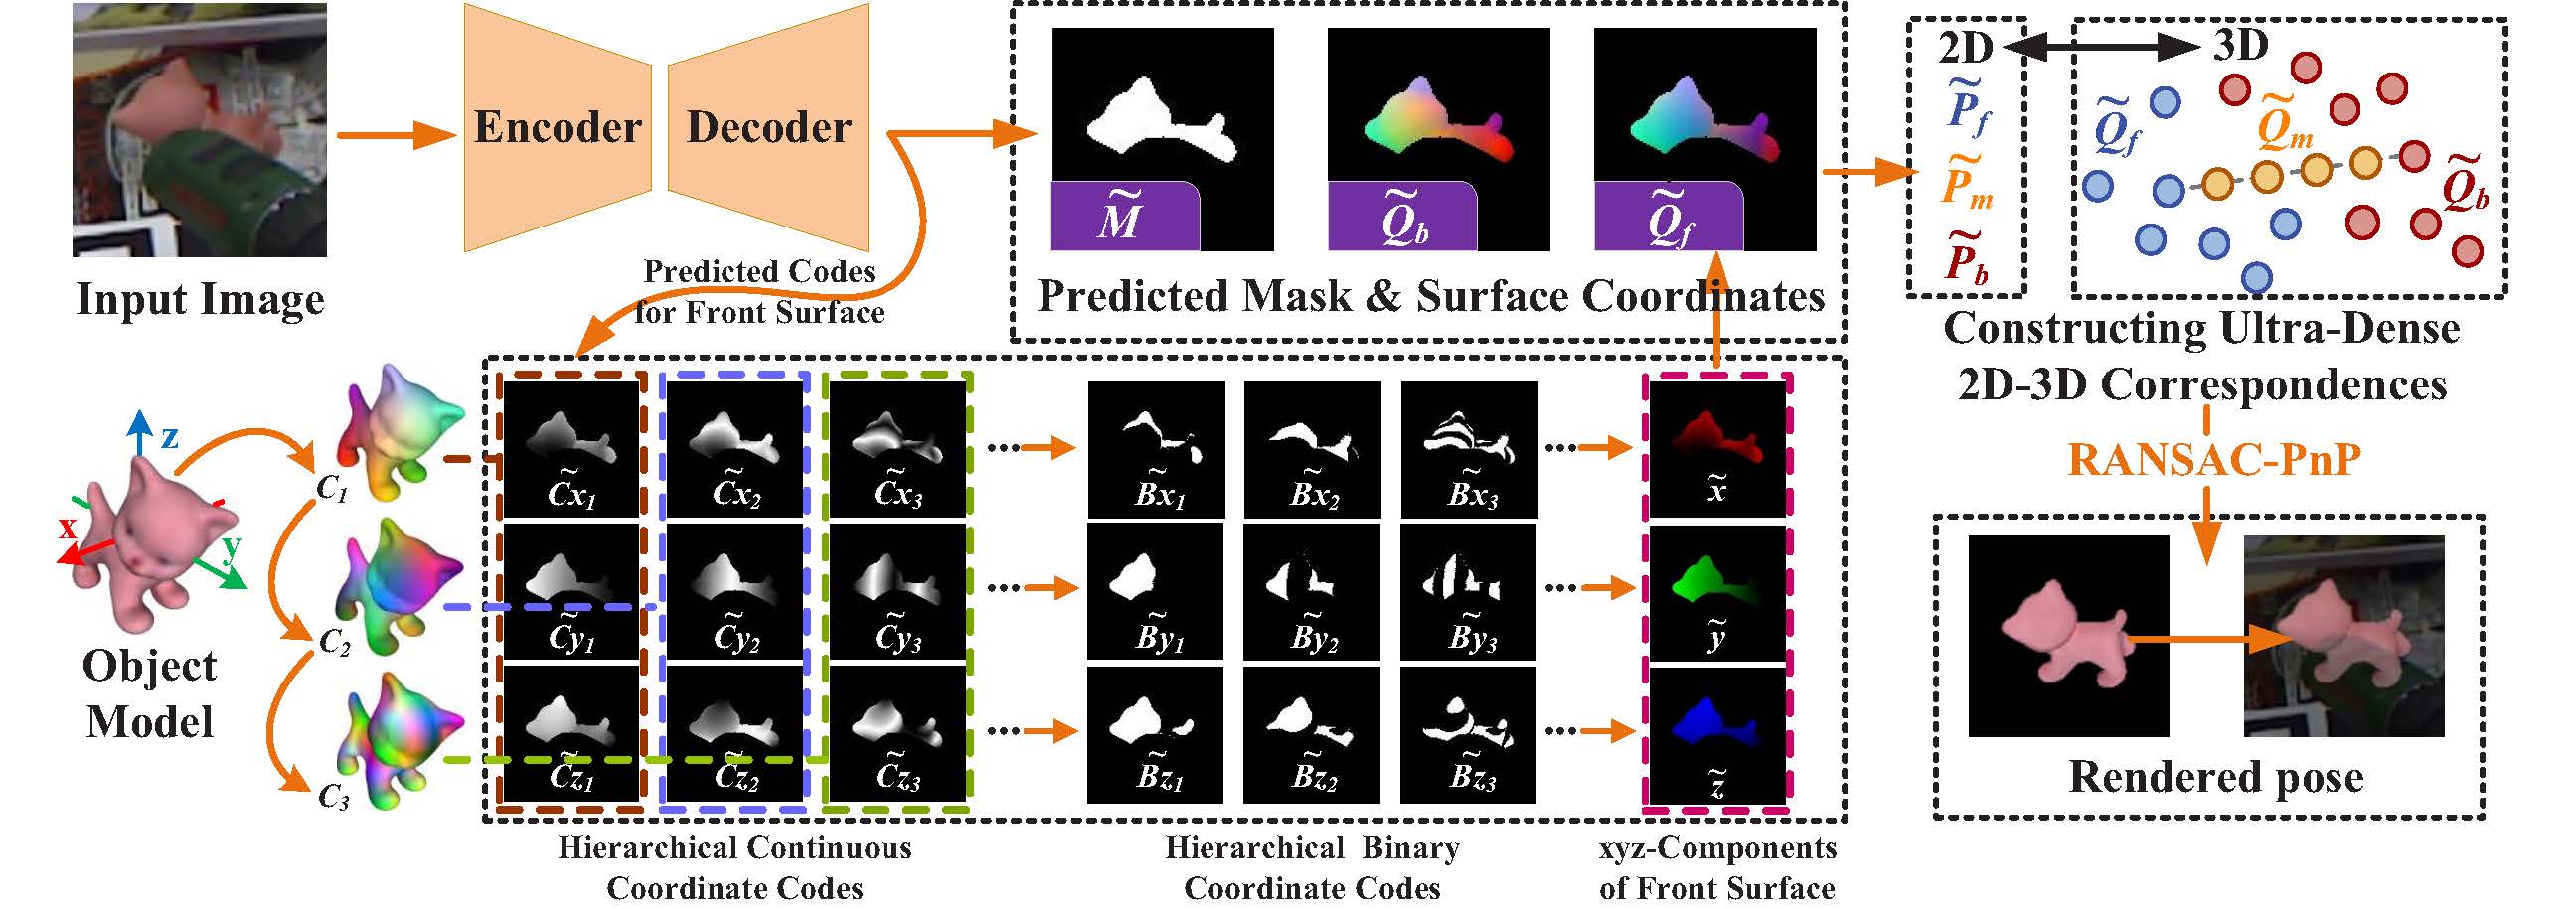
论文中的 HccePose(BF) 网络结构与位姿求解流程。
从检测到位姿
YOLO 提供目标区域,HccePose 为对应物体预测掩码及表面坐标。结合匹配分辨率的相机内参,PnP 求解物体到相机的位姿。检测器可以识别多个类别;位姿权重按物体加载。
层次坐标编码与对应关系
HCCE 分别编码物体坐标的三个分量。网络同时预测掩码和前后表面编码,解码后得到物体坐标系下的三维点。一个前景像素沿相机射线对应最近与最远的两个表面交点,因而可以构建两组 2D–3D 对应。
| 阶段 | 数据流 |
|---|---|
| 检测与裁剪 | YOLO 提供实例区域;图像缩放、补边及裁剪变换决定像素坐标的映射。 |
| 网络预测 | 逐物体网络预测掩码与前后表面编码。 |
| 建立对应 | 解码三维坐标,与掩码中的像素位置配对。 |
| 求解位姿 | 结合相机内参用 PnP 求解 X_camera = R @ X_model + t。 |
检测器可包含多个物体类别,每类可检测多个实例;HccePose 权重按物体分别训练和加载。换新物体的完整流程见物体准备、场景渲染、检测器、坐标标签与位姿训练。
深度与可选后端
MegaPose 从 HccePose 位姿继续精修,支持纯 RGB 或配准 RGB-D。WAPR 的当前公开接入从原图掩码、配准深度和米制网格估计位姿并评分,不依赖 HccePose 初值。它们不是同一个调用模式,输入与单位对照见精修接口。
Method and pipeline
One pixel, two surface points
The nearest and farthest intersections along a camera ray correspond to the front and back surfaces. HccePose(BF) predicts hierarchical continuous coordinate codes for both surfaces and pairs the decoded 3D points with image pixels.
HccePose(BF) network architecture and pose estimation pipeline, from the published paper.
From detection to pose
YOLO supplies object regions. HccePose predicts masks and surface coordinates for the corresponding object. PnP uses image-matched intrinsics to recover the object-to-camera pose. One detector can identify multiple categories; pose weights are loaded per object.
See the paper and API contract.
Hierarchical coordinates and correspondences
HCCE encodes the three object-coordinate components separately. The network predicts masks and front/back surface codes, which decode to 3D points in the object coordinate system. A foreground pixel corresponds to the nearest and farthest intersections along its camera ray, providing two sets of 2D–3D correspondences.
| Stage | Data flow |
|---|---|
| Detect and crop | YOLO proposes instance regions; resizing, padding and crop transforms define pixel mappings. |
| Predict | Per-object networks estimate masks and front/back codes. |
| Match | Decode 3D coordinates and associate them with masked pixel locations. |
| Solve | Use pixel intrinsics and PnP to estimate X_camera = R @ X_model + t. |
A detector may recognize several categories and multiple instances per category. HccePose checkpoints are trained and loaded per object. For a new object, follow mesh preparation, rendering, detector training, coordinate labels and pose training.
Depth and optional backends
MegaPose refines HccePose poses using RGB or registered RGB-D. The current public WAPR integration estimates poses and scores from original-image masks, registered depth and meter meshes, without HccePose pose seeds. These are distinct entry points; see refinement interfaces for inputs and units.
This page explains the published method. The original paper figure is preserved. See Tester and results for actual calls and array shapes.